
Today we’re releasing Alpha 2 of Pipecat PhoneLLM: a blazingly fast, open-weights text model designed to be integrated into voice agent pipelines.
This time, we’re releasing two variants of the model:
- PhoneLLM Mini uses the same tiny 30B/A3.5B MoE architecture as Alpha 1, and is a great choice when speed and size are the top priority.
- PhoneLLM Max is a larger 120B/A12B model. Use this when you need stronger intelligence and better accuracy, while still achieving industry-leading inference speed.
The key improvements in Alpha 2, aside from some major accuracy enhancements due to our expanded dataset, are the addition of microthinking to PhoneLLM Max, support for Pipecat Flows integration, and reduced sensitivity to different prompting styles, making the model more flexible.
We've also updated our PhoneBench benchmark to test a wider range of model capabilities, such as error correction.
Microthinking
Most LLMs which emit reasoning tokens generate several paragraphs (or even pages) of thought for each request. This increases cost and latency, and high accuracy with reasoning disabled was a major goal for PhoneLLM Alpha 1.
In Alpha 2, we’ve found that allowing PhoneLLM Max to output a single sentence of reasoning has a measurable impact on whether it calls the correct tools. We refer to this as “microthinking”.
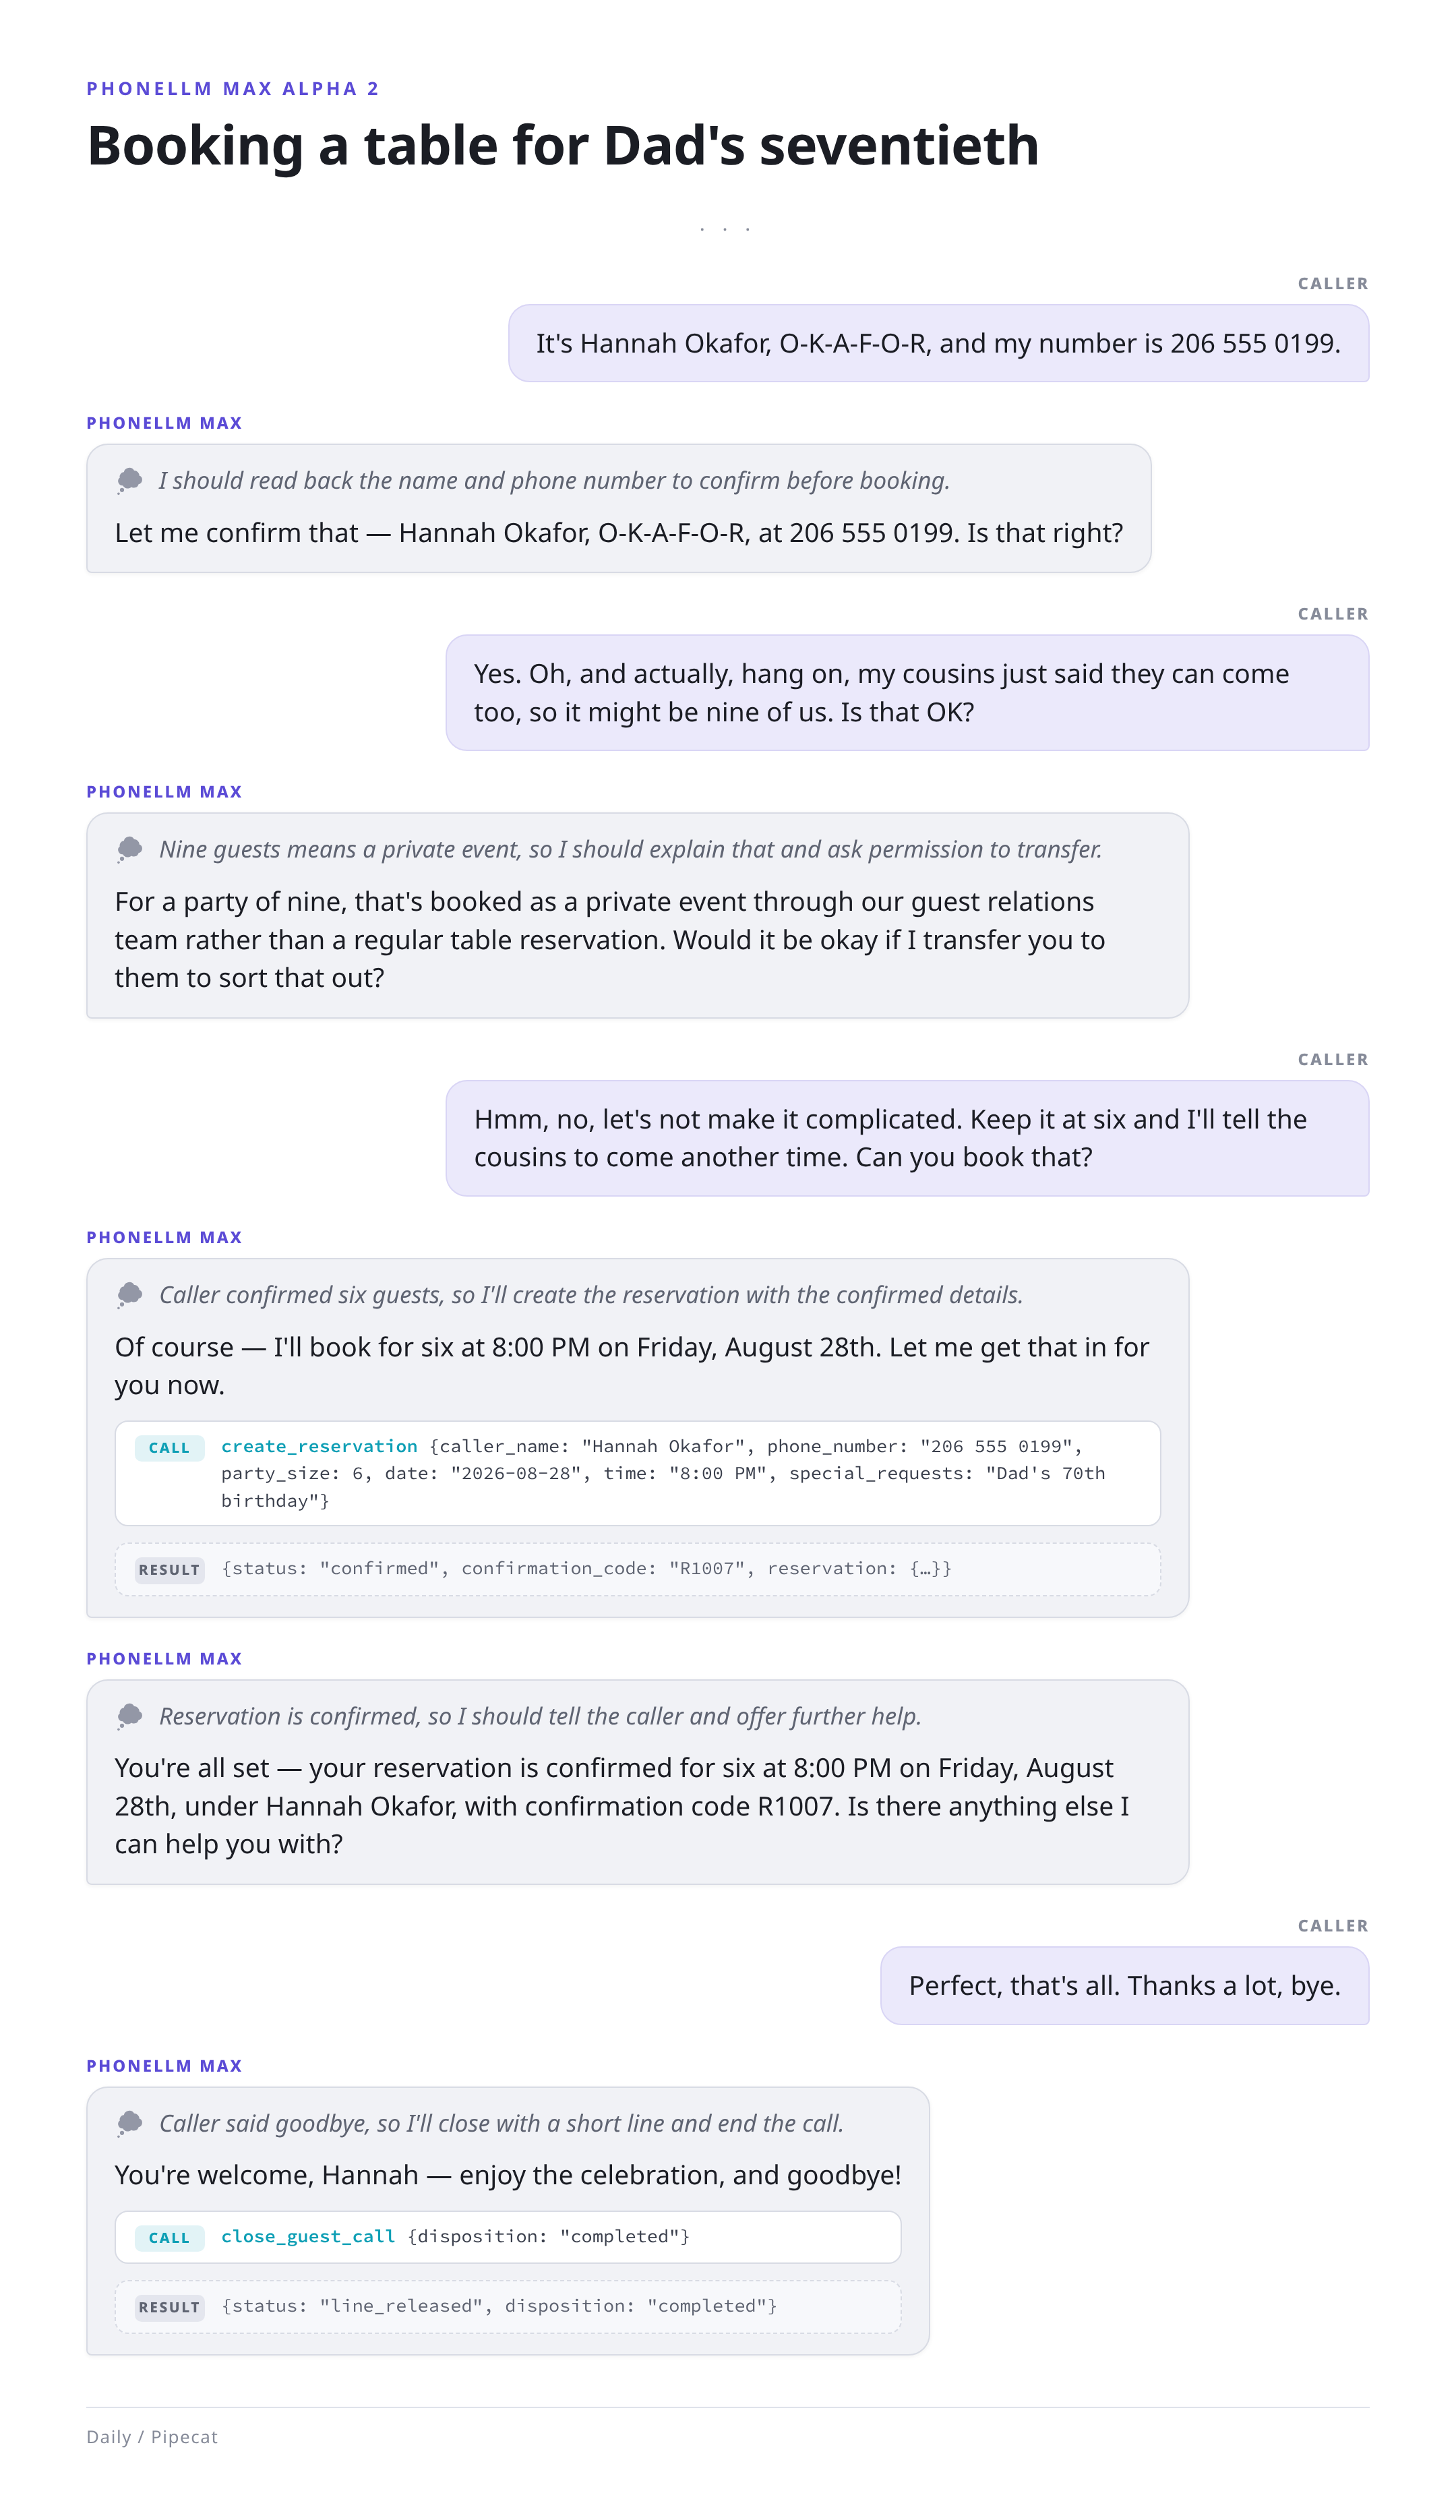
Microthinking is a good compromise between the accuracy of full reasoning mode, and the latency/performance of having reasoning disabled. A single sentence, when emitted at PhoneLLM’s high inference speed, has a negligible impact on response time.
Pipecat Flows support
Pipecat Flows is a framework for structured conversations with voice agents. LLMs are nondeterministic and often make mistakes when following instructions, and a programmatic harness like Pipecat Flows can reproducibly guide the LLM through a complex sequence of steps, while keeping each individual step simple.
Smaller, cheaper models like PhoneLLM are a perfect fit for this: the constraints and guidance of the harness reduce the likelihood of mistakes, as the model doesn’t need to make complex decisions on its own.
We’ve trained PhoneLLM Alpha 2 on synthetic Pipecat Flows sessions, meaning it already understands the prompting format and conversation structure, and can be used as a drop-in replacement for larger models.
In our testing with real customers, we’ve found that PhoneLLM Max brings calls to a successful resolution at a higher rate than GPT-4.1 when integrated into Flows, with around half the latency and a fraction of the cost.
More flexible prompting
For Alpha 2 we’ve expanded our training dataset to cover a wider range of use cases and prompting styles.
This means less time spent tweaking your prompts to get the most out of PhoneLLM.
PhoneBench updates
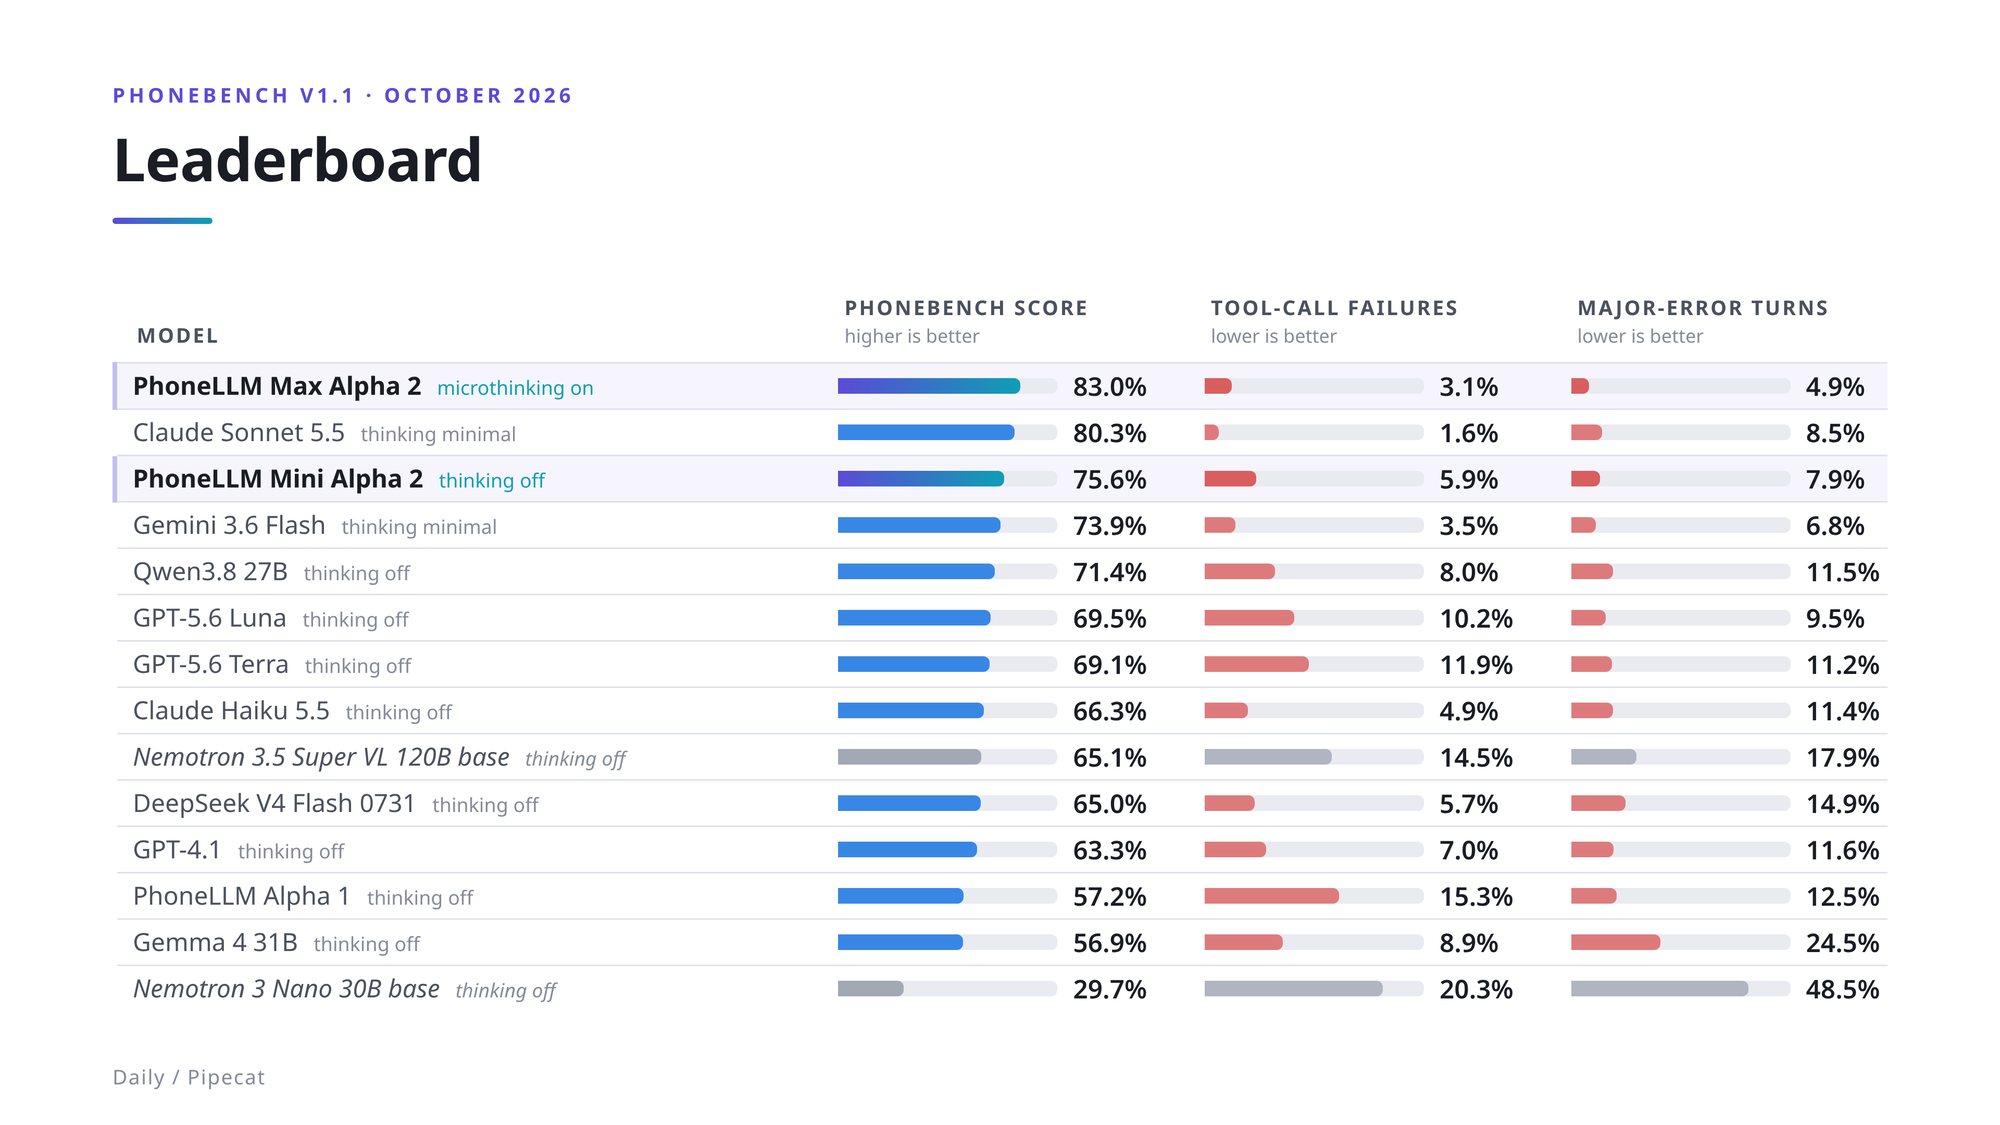
For this release we’ve improved our PhoneBench benchmark to cover several new cases the previous model struggled with.
Among other things, PhoneBench now checks whether the model can correct mistakes from earlier in the conversation, follow sequences of instructions, and handle Pipecat Flows scenarios.
We also have separate measurements for how often the model makes a mistake when calling a tool, and how often the model makes a major mistake of any kind during the conversation.
View the full leaderboard here.
Running the model
PhoneLLM is an open-weights model. Our partners AWS, Baseten, Cloudflare, and Modal offer PhoneLLM as click-to-deploy models and hosted API endpoints.
Inference partners
- AWS SageMaker AI - Deploy to AWS SageMaker inference clusters. Your coding agent can guide you through deploying to SageMaker.
- Baseten - PhoneLLM is a Baseten Dedicated Inference model, allowing you to deploy an optimized PhoneLLM instance from the Baseten CLI or dashboard.
- Cloudflare - PhoneLLM Mini on Cloudflare's global Workers AI serverless inference platform, priced at $0.06 per M input tokens, $0.24 per M output tokens
- Modal - Start an optimized endpoint for Mini or Max using Modal's Endpoints service. See the PhoneLLM entries in Modal's model library.
Model weights
You can run the PhoneLLM models on your own hardware, or set up PhoneLLM inference clusters from scratch in the cloud. Links to model weights:
- PhoneLLM Mini NFVP4 - fits on an NVIDIA RTX 5090
- PhoneLLM Max NVFP4 - fits on an NVIDIA DGX Spark
- PhoneLLM Mini FP8 - NVIDIA H100
- PhoneLLM Mini BF16 – Recommended for production serving at scale (NVIDIA B300, B200, H200, or RTX PRO 6000)
- PhoneLLM Max BF16 – Recommended for production serving at scale (2x NVIDIA B200/B300 with TP2)
vLLM
When making requests, set temperature to 0.0. For Mini, turn reasoning off, and for Max, turn reasoning on to enable microthinking.
PhoneLLM Mini
The following command runs the model on a single GPU, such as an NVIDIA B200, H200, or RTX PRO 6000.
On a B200 GPU, we measured TTFT as 17ms, and aggregate decode at 10k tok/s.
vllm serve pipecat-ai/phonellm-mini-alpha-2 \
  --served-model-name phonellm-mini-alpha-2 \
  --trust-remote-code \
  --dtype bfloat16 \
  --max-model-len 32768 \
  --gpu-memory-utilization 0.90 \
  --max-num-seqs 256 \
  --enable-prefix-caching \
  --async-scheduling \
  --mamba-ssm-cache-dtype float32 \
  --enable-auto-tool-choice \
  --tool-call-parser qwen3_coder
PhoneLLM Max
The larger variant of PhoneLLM has been tested with a 2x B200 configuration, and will run with similar performance on 2x B300.
We measured TTFT at ~27ms, and aggregate decode at ~6k tok/s.
PhoneLLM Max also supports MTP, which can double decode speed when there are few active parallel calls.
Note: Max requires thinking to be turned on, and due to microthinking the latency cost is minimal. In future versions we’re considering training Max to work with thinking either on or off.
vllm serve pipecat-ai/phonellm-max-alpha-2 \
  --served-model-name phonellm-max-alpha-2 \
  --tensor-parallel-size 2 \
  --dtype bfloat16 \
  --max-model-len 32768 \
  --gpu-memory-utilization 0.90 \
  --max-num-seqs 256 \
  --kv-cache-dtype fp8 \
  --enable-prefix-caching \
  --async-scheduling \
  --mamba-ssm-cache-dtype float32 \
  --enable-auto-tool-choice \
  --tool-call-parser qwen3_coder \
  --reasoning-parser nemotron_v3
Our training process
Like Alpha 1, the new PhoneLLM Mini is based on NVIDIA’s Nemotron 3 Nano, with 30B total parameters, and 3.5B active parameters. PhoneLLM Max is built on Nemotron Super 3.5 VL, a 120B model with 12B active parameters.
We use NVIDIA’s NeMo Framework for training, specifically Megatron Bridge and NeMo RL. The NeMo framework has great support for the Nemotron models, and takes the hassle out of finding a working training configuration.
It also makes it easy to scale training across multiple GPUs and nodes: to train PhoneLLM Max, we need 16x B300 GPUs across two machines.
PhoneLLM is trained on fully synthetic datasets, designed to mimic real-world voice agent use cases. We use a variety of open-weights models as teachers — these teacher models generate high quality responses which the student model is then taught to imitate.
To make the model as flexible as possible, we train on a variety of data shapes: different prompting styles, tool sets, harnesses such as Pipecat Flows, and so on.
So far, our PhoneLLM releases have been full-weights fine-tunes using SFT, which we’ve found is fast, relatively inexpensive, and gives predictable improvements. We have ongoing experiments with reinforcement learning — for example, we’ve seen some improvements by applying a final GRPO stage to our training pipeline, and it’s likely that we’ll enable this for future releases of the model once we’re confident in the quality.
Never miss a story
Get the latest direct to your inbox.